Follow the latest research
alphaXiv connects papers, researchers, and organizations, grounding its answers in the underlying work.
 Together AI
Subtracting the sampler’s expected token scores cancels mismatch-driven drift, stabilizing language-model reinforcement learning under severe quantization and stale rollouts.

 Stanford
A lightweight policy can correct delayed vision-language-action commands using current observations, enabling reinforcement-learning adaptation for dynamic real-world manipulation.

A shared factorized predictive core supports reusable latent state representations across vision, biology, clinical forecasting, control, molecular dynamics, and physical systems.

Researchers to follow
View all
Are you a researcher? Find your profile
 NVIDIA
 NTU
As coding agents move from supervised code completion to unattended, around-the-clock exploration, their work expands from isolated predictions into long trajectories of reasoning, tool use, and feedback. Token efficiency therefore becomes important for scaling recursive self-improvement. We take an RSI-inspired approach at the harness layer, scaling auto-research loops across increasingly numerous and diverse environments for harness rollouts. At this scale, the process yields reusable improvements that transfer beyond their development setting, moving automated harness discovery toward production-level outcomes. Four mechanisms survive selection and form SoL-Pi, spanning action execution, context compaction, observation handling, and delegated reading. On the 51-task EdgeBench evaluation, SoL-Pi achieves performance comparable to Pi across GPT-5.6 Sol and Opus 5 while reducing recorded token traffic by 44.7-49.0% and API cost by about one third. In other words, estimated hourly savings are $8.75-$13.50 relative to native Codex and Claude Code harnesses, and $4.36-$5.71 relative to Pi.

 Shanghai Innovation Institute
 HUST
Vision-language agents can adapt robot behavior from human videos, goal images, and interaction history without updating task-specific parameters.

 NUS
Answer-matched experiments show that most reasoning gains come from distillation itself, while reference benefits vary with the model and student training trajectory.

 Deepseek
Cross-layer KV reuse, FP4 caching, and bounded replay make million-token multimodal agents more practical by sharply reducing context-memory requirements.

 ZJU
 Alibaba Group
Training agents with privileged guidance early, then removing it when alignment stalls, improves reward-driven learning without requiring skills at inference.

 PKU
 HKU
Aligned human touch data improves dexterous robots’ predictions of future visual and contact dynamics without requiring additional robot interaction.

 UMass Amherst
 Emory University
Coding-agent harnesses should be tailored to model capability, task type, and context budget rather than adopted as universal defaults.

 NYU
Architectural depth growth and boundary normalization can improve language-model scaling exponents, making compute-efficiency gains compound as pretraining budgets increase.

Researchers to follow
View all
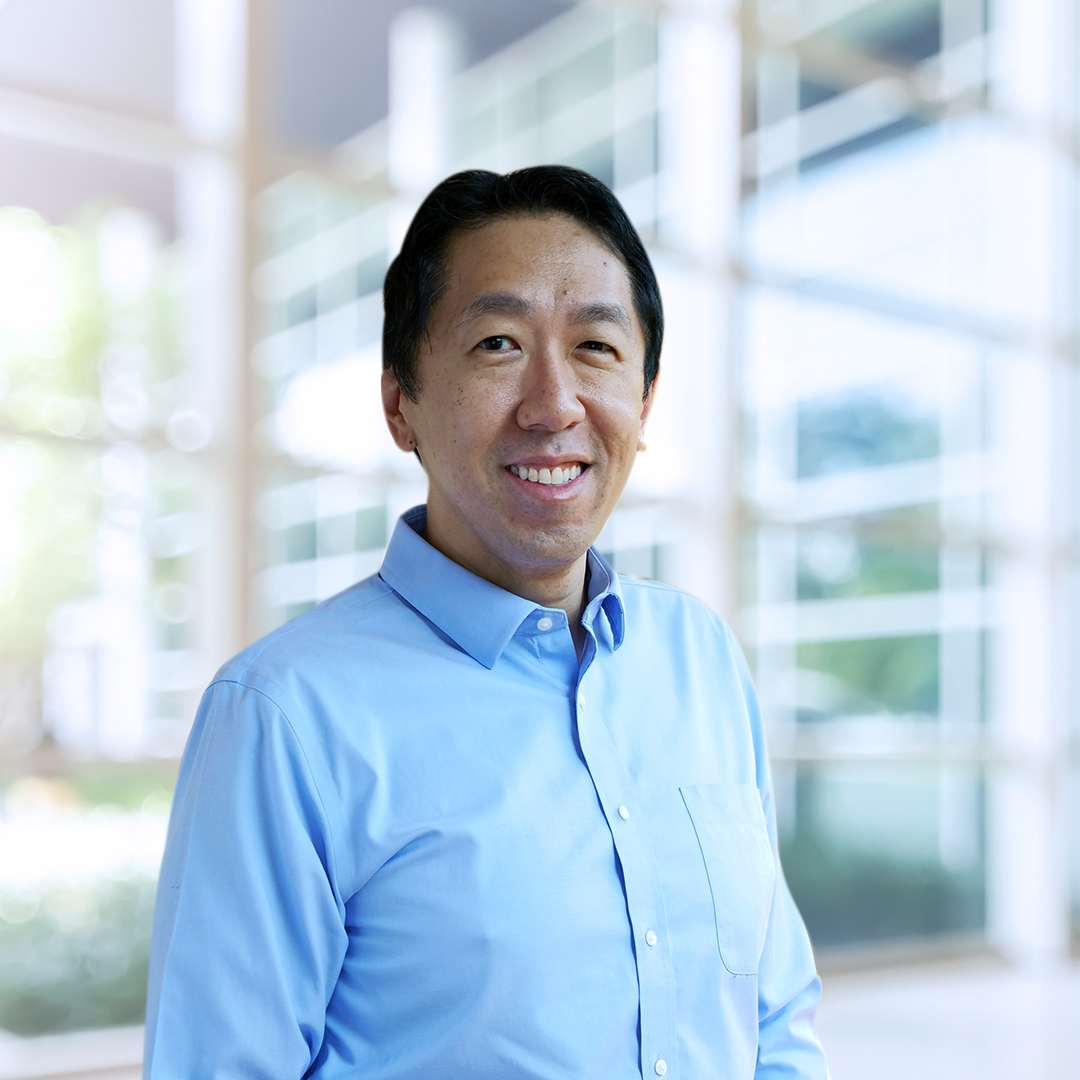
Andrew Ng
Managing Partner
AI Aspire, Managing General Partner @ AI Fund, Founder @ DeepLearning.AI, Adjunct Professor, CS @ Stanford University, Chairman and Co-Founder @ Coursera
A tabular foundation model now handles temporal, grouped, text-rich, multimodal, and wide datasets while improving predictive distributions and relational learning.

 EPFL
 Google
A calibrated multi-view benchmark and observation-guided representation make real splashes reconstructable for novel-view rendering, motion interpolation, and appearance editing.

 ETHZ
 NVIDIA Research
A render-free reinforcement-learning teacher can improve camera-based driving policies through on-policy supervision, avoiding the exploration burden of rendered reinforcement learning.

This document provides an extended and rigorous framework dedicated to the geometric analysis of the 3D incompressible Navier-Stokes equations [4]. We comprehensively develop geometric proofs related to decay estimates, blow-up profiles, and the foundational partial regularity theory of Caffarelli, Kohn, and Nirenberg (CKN). We examine in detail the Hausdorff dimension of potential singular sets, local monotonicity inequalities, and the spectral analysis of linearized operators to classify singularities into stable and unstable manifolds.

Expert-verified scientific code environments let agents learn from executable simulations, graded feedback, and reusable tasks spanning diverse research software.

 SJTU
 Shanghai AI Lab
Sparse, well-separated critic supervision helps PPO track changing state values within long reasoning responses and learn stronger policies.

 CMU
 Columbia
Predicting dense 3D motion from sparse tracks enables robot-free dynamics pretraining that transfers to unseen objects and manipulation tasks.

A Git-backed research graph lets independent coding agents preserve, verify, and build on discoveries instead of restarting experiments from scratch.

 Goodfire
Simple activation probes can detect reward hacking during long agent rollouts, predict later exploits, and reveal cheating behaviors that language-model monitors miss.
